How to Get Cited by ChatGPT: The Mechanism, the Work, and the Honest Timeline
What actually determines whether an AI engine names your brand, the four layers of work that move it, and the parts of the popular playbooks that stopped working or never did, with the diagrams that make the mechanism obvious.
On this page (8 sections)
The Short Answer
ChatGPT and Perplexity decide which brands to recommend by retrieving sources they trust for the buyer question, then naming brands that recur across several independent sources in that set. A brand that only appears on its own site rarely clears contested commercial questions; corroborating earned coverage and genuine community mentions matter, and each engine's retrieval blend can surface a different source set.
Four layers of work follow from that mechanism: make your own pages easy to retrieve and quote; earn coverage and mentions in the independent sources engines retrieve for your category; stay present where buyers already talk; and measure at prompt level, with branded and non-branded visibility kept separate. To see where you stand, talk to us.
First, Understand What a Citation Actually Is
If you need the grounding first, our guide to what ChatGPT search visibility is covers the definition, how it differs from SEO, and which tools track it. If the acronyms are the confusion, our GEO vs AEO vs AI SEO comparison sorts out which term describes which part of the work.
A citation in an AI answer is a retrieval event, not a memory. When someone asks ChatGPT a buyer question, the engine runs live search and licensed feeds, pulls a set of pages, and synthesises an answer from what came back. Ahrefs' study of 1.4 million ChatGPT prompts (April 2026) found 88% of the URLs ChatGPT cites are taken directly from search. The engine has no private opinion of your brand; it has whatever the retrieval layer returned in the last few seconds.
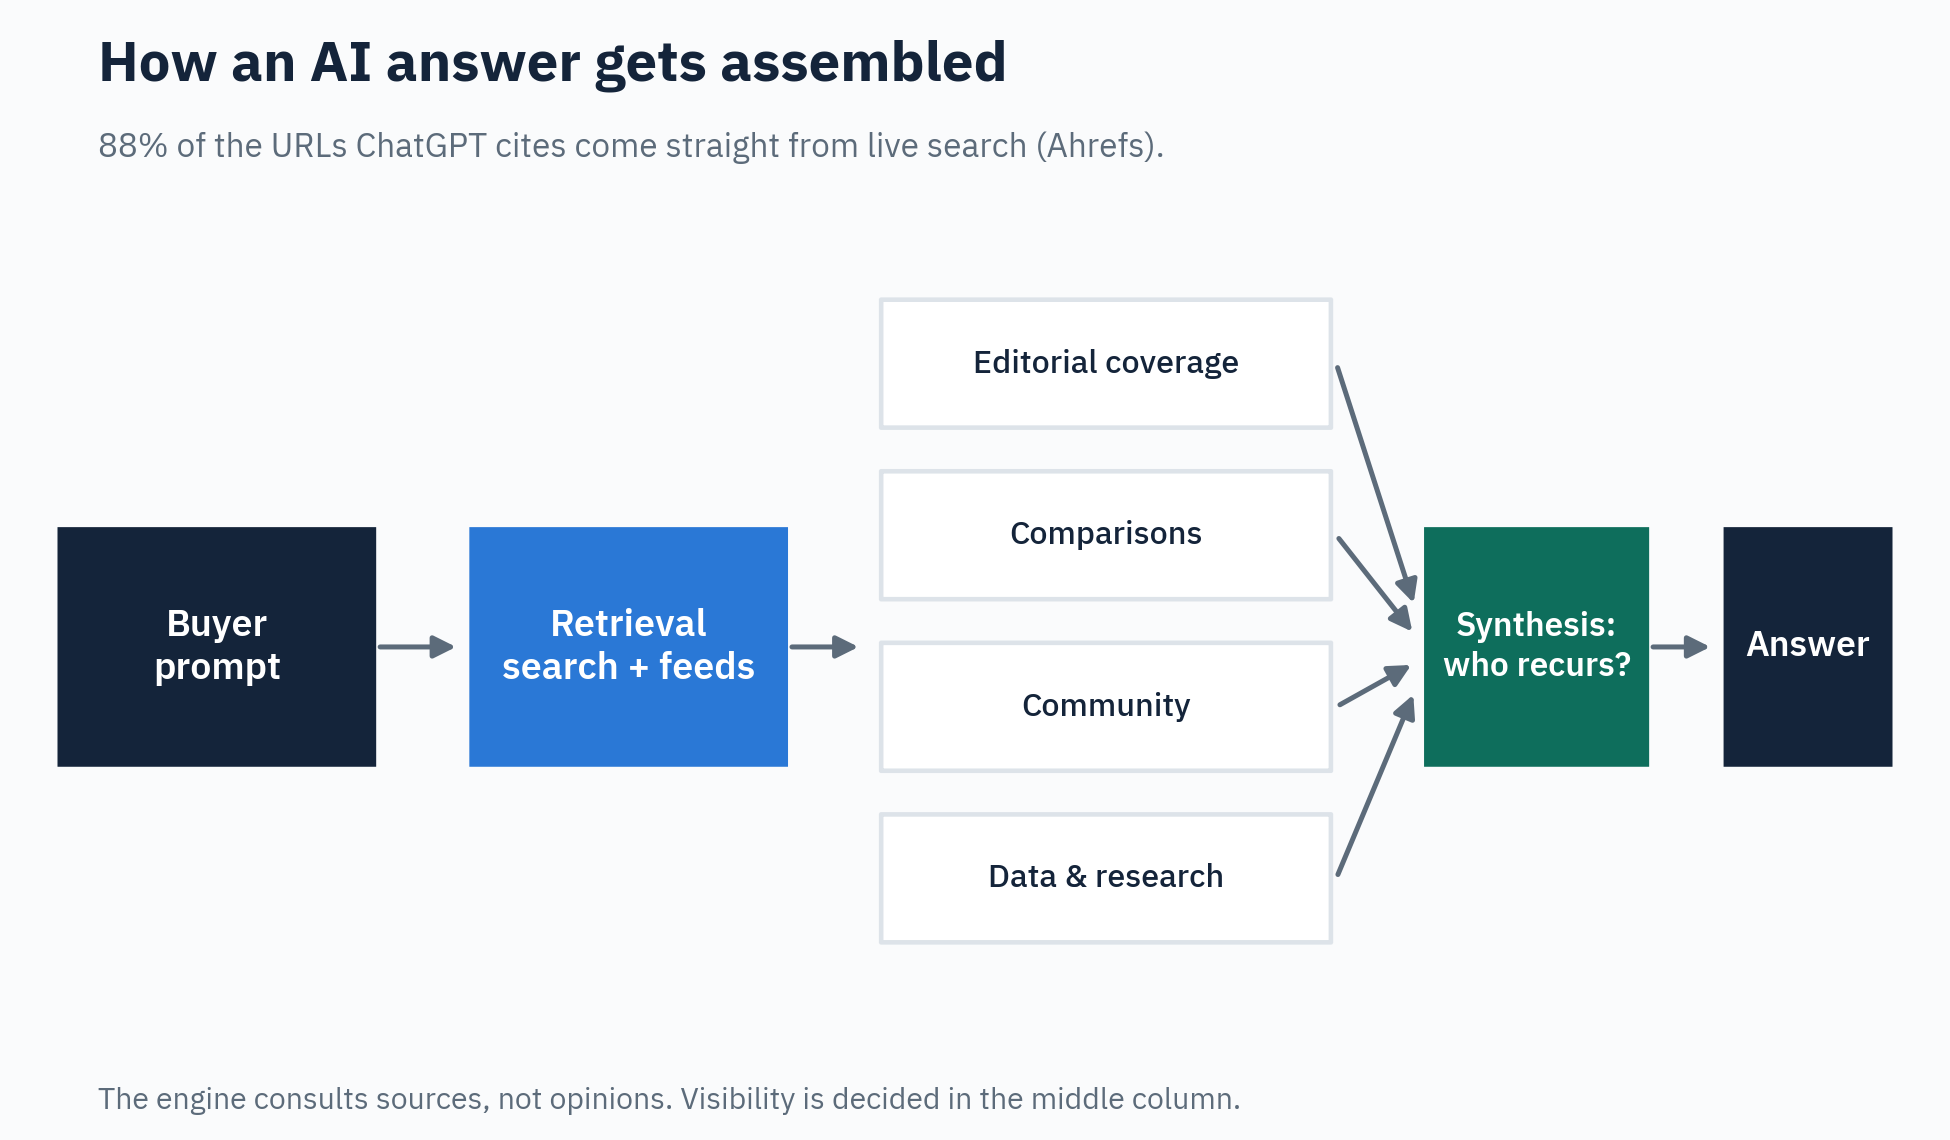
Two consequences follow. Retrievability is a precondition: if your pages and your coverage do not surface in search, they do not exist to the engine, which is why the SEO foundation carried over intact. And deletion is fatal: a source that disappears stops citing you the same day, which matters for anyone renting their presence.
Second, Understand Who Supplies the Citations
The retrieved set is not a neutral sample of the web. Muck Rack's 2026 analysis of 25 million AI citations found earned media accounts for 84% of them, while paid and advertorial content accounts for 0.3%. Reddit is the single most cited domain across engines, and community content generally is weighted far above anything money can touch directly.
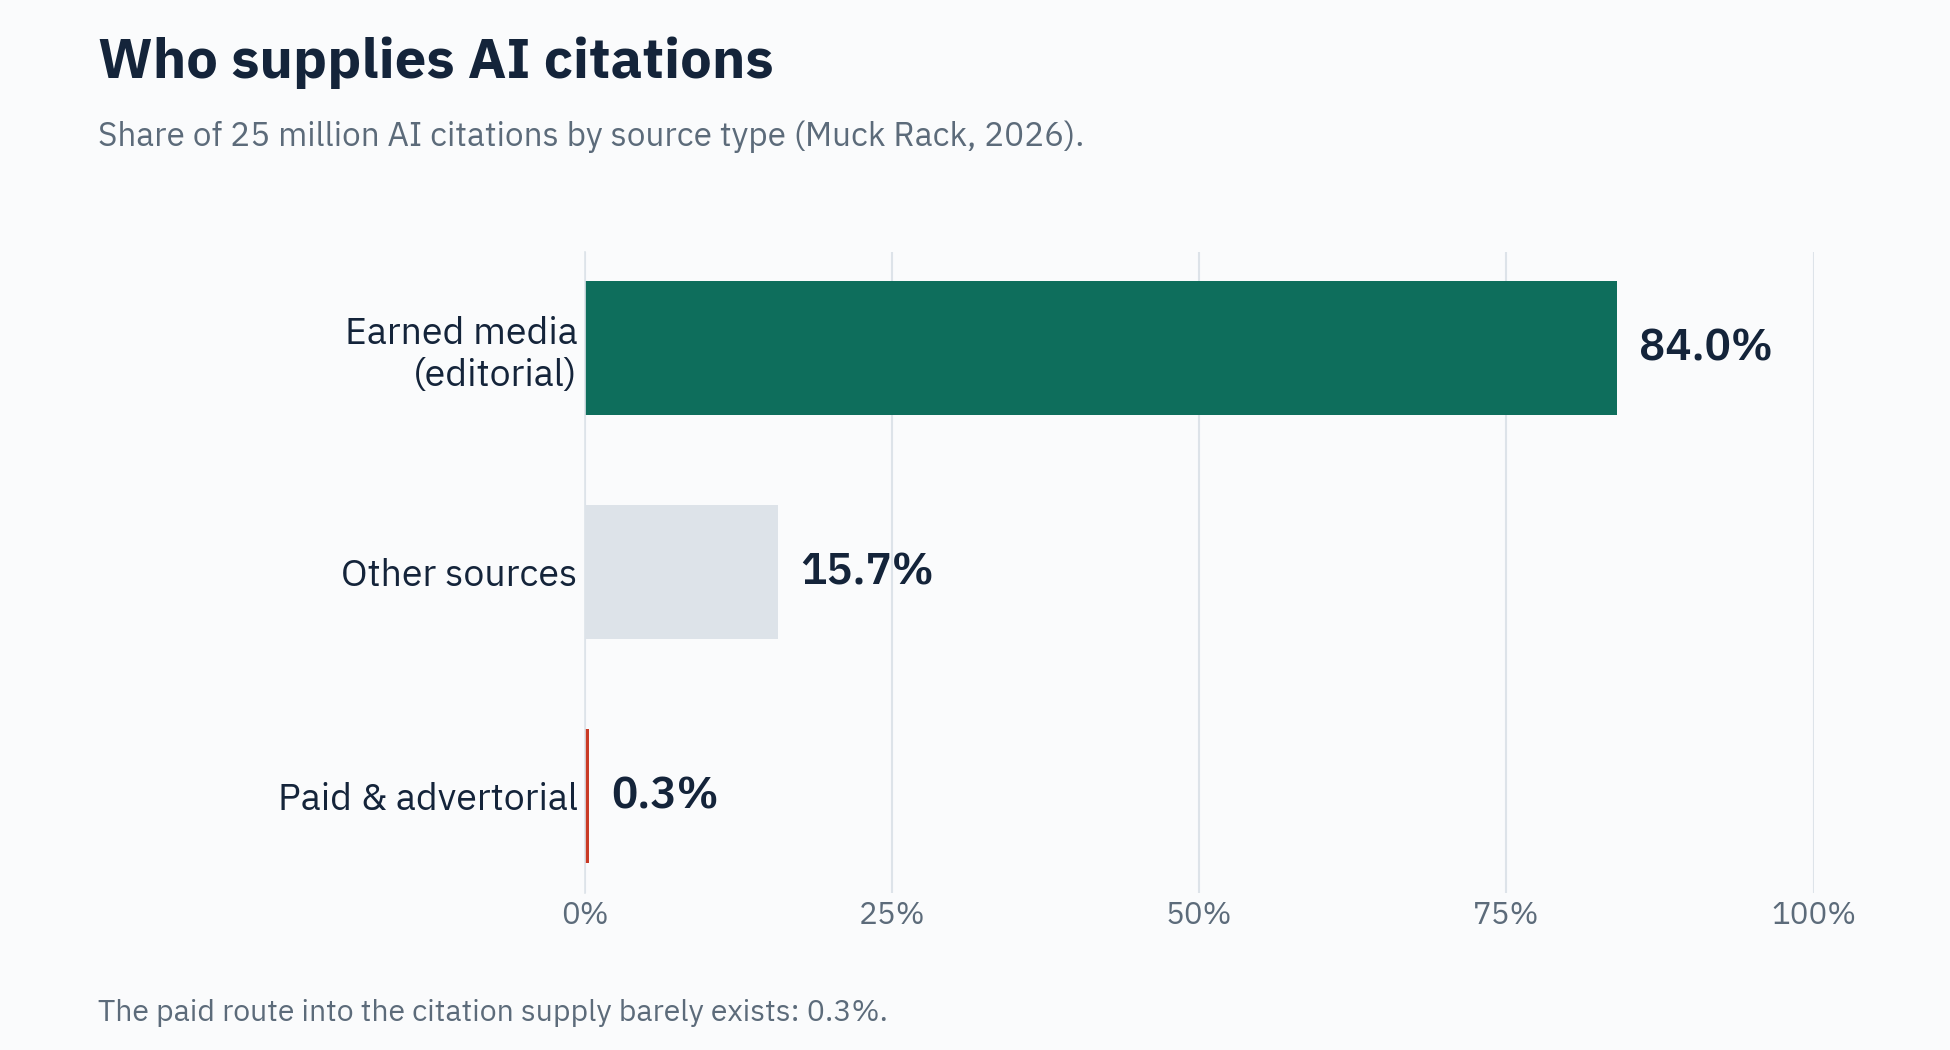
Read that chart as a budget instruction: the supply of AI citations is editorial and community, so that is where visibility spend has to end up, whatever channel it travels through.
Third, Understand the Threshold: Corroboration
This is the mechanism behind most visibility gaps. In the synthesis step, engines name the brands that appear across several independent retrieved sources, and drop the ones supported by a single source, including the brand's own site. To the engine, one self-interested source is an assertion; recurrence across independent sources is a fact.
The accumulated pattern of that recurrence is citation equity, the asset the rest of this guide is about building. A well-built page can become a cited source for a competitive question within days of publication while the brand behind it stays out of the named recommendations, until other sources corroborate it.
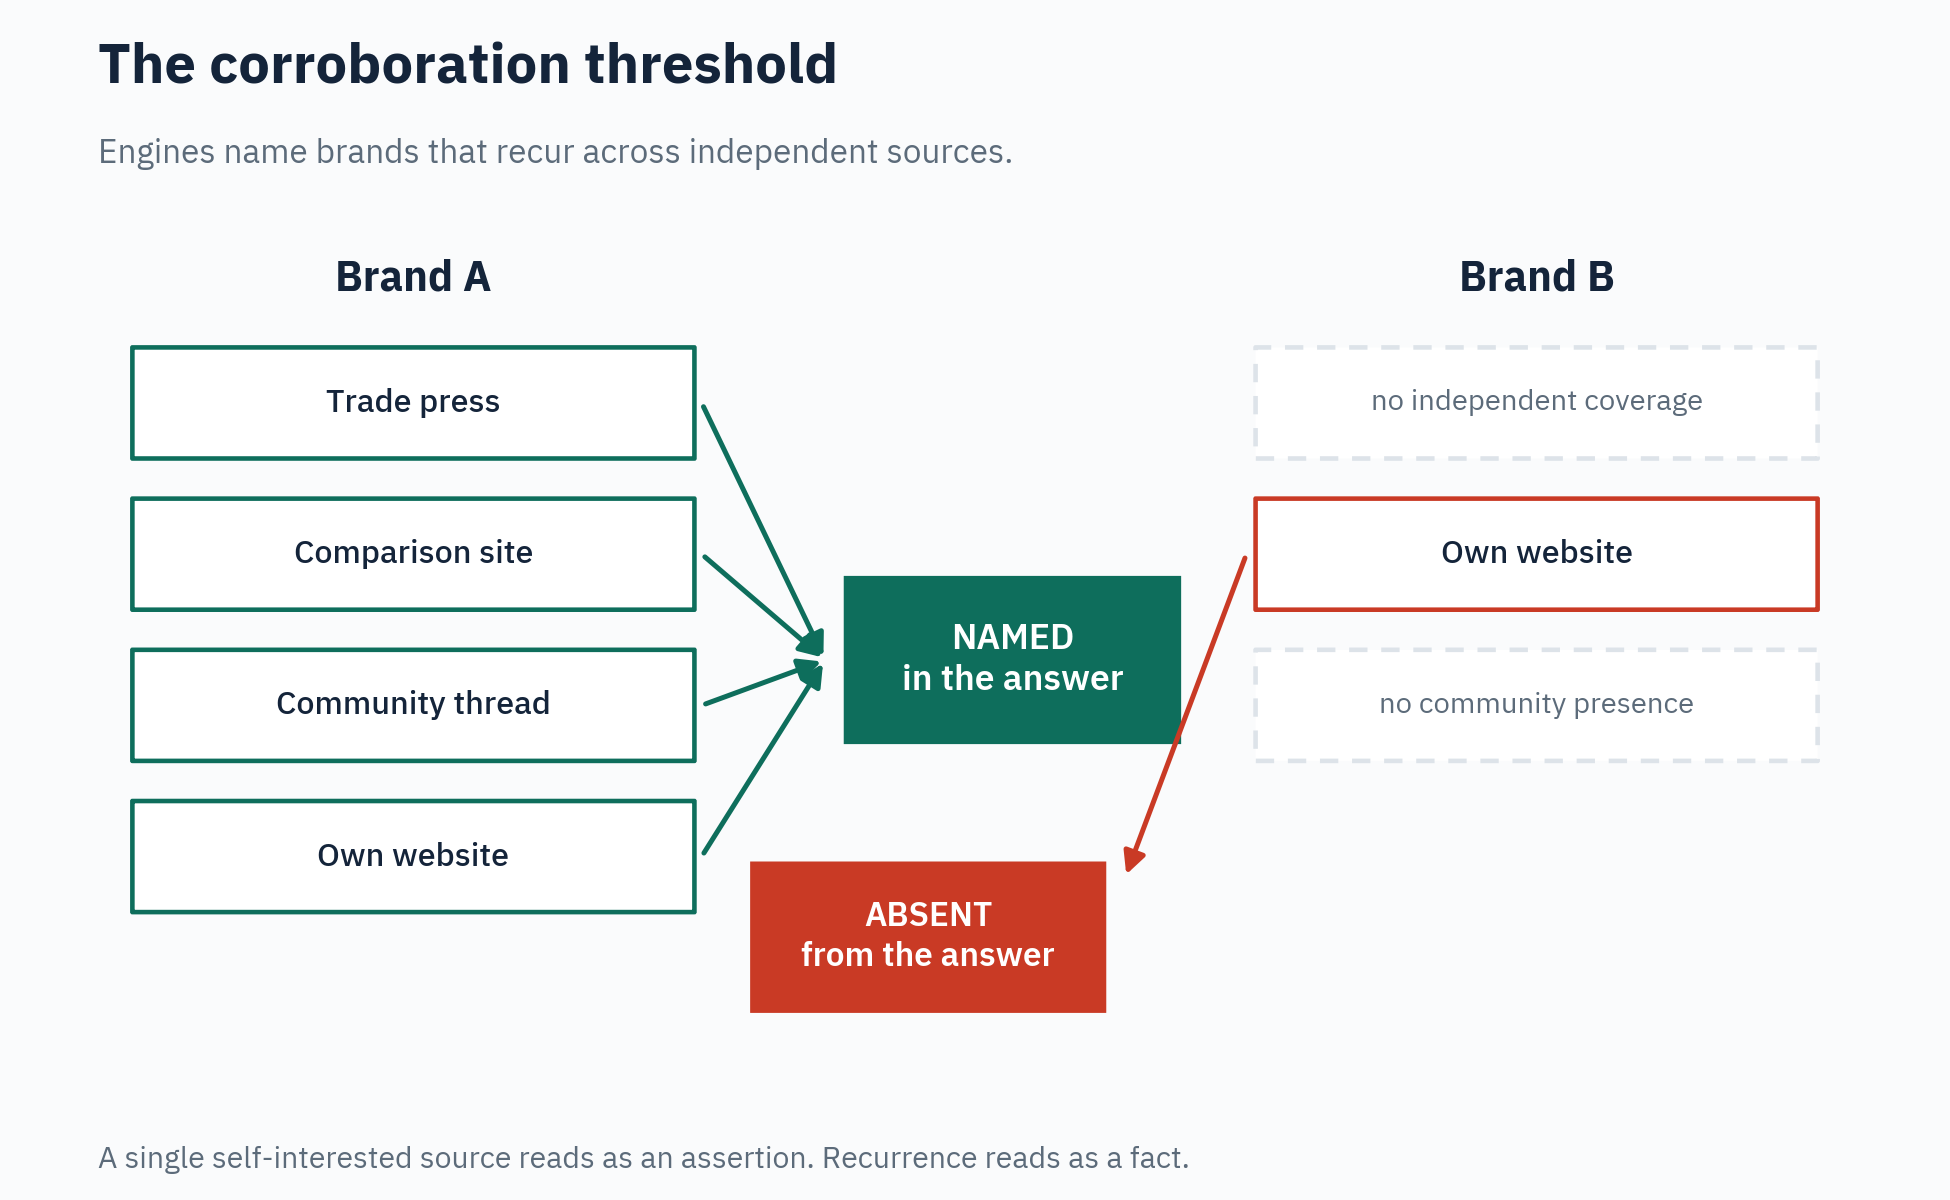
This is also why branded and non-branded visibility differ so much. Ask an engine about your brand by name and it retrieves your site and coverage about you: near-automatic visibility. Ask the question a buyer who has never heard of you asks, and it retrieves the sources trusted on the category, where you may appear nowhere. The two numbers can differ widely, which is why any visibility figure that blends them is concealing the finding.
The Work, in Order of Leverage
Layer one: make your pages worth lifting. The founding academic research on generative engine optimisation found conventional SEO tweaks did little inside generated answers, while adding statistics, quotations and cited sources raised a page's share of the answer by up to 40% on the paper's own measure, for pages that had already been retrieved. In practice: answer the question in the opening paragraph, use concrete numbers, name your sources, structure comparisons as comparisons, and keep a clean summary near the top of every substantive page.
This layer is cheap and fully in your control, and on long-tail questions with few good sources it can earn citations within weeks. Its ceiling is just as clear: it improves what happens when your pages are retrieved, and does nothing to corroborate you elsewhere.
All of it assumes AI crawlers can fetch your pages in the first place. A robots.txt rule or a firewall setting can shut them out without anyone noticing; our free AI SEO tools check both in under a minute.
An llms.txt file, a plain-text map of your key pages for language models, sits at the edge of this layer. No AI engine has confirmed that it reads one, so treat it as a tidy extra rather than a lever; our free llms.txt generator builds one from your sitemap in seconds.
Layer two: earn the corroborating citations. The decisive layer, and the slow one. Coverage in the publications engines retrieve for your category, editorial mentions, independent comparisons that include you, data journalists citing your research.
The most reliable source of all of it is original data: a study with a defensible method gives journalists a story that cannot be written without citing you, and every later article on the topic inherits the citation. This is the mechanism Ranking Atlas's AI SEO service is built on, documented in our citation equity guide; the arithmetic of what campaigns produce is in our link benchmarks guide. Mentions matter here as much as links: Ahrefs' study across 75,000 brands found branded mentions correlate three times more strongly with AI visibility than backlinks do.
Layer three: a real community presence. Community discussion is among the heaviest-weighted source types, and it is the one layer that punishes manufacturing. Platforms run LLM-based detection against coordinated seeding and delete it retroactively, and since citation is retrieval, deleted posts take their citations with them the same day. The durable version is unglamorous: founders and teams taking part where their buyers talk, and building the kind of brand people mention when nobody paid them.
Layer four: measure, or the other three are faith. A fixed panel of the prompts your buyers ask, run across ChatGPT, Perplexity, Gemini and AI Overviews on a schedule. Log who gets named and which sources get cited, benchmark against named competitors, and start from a baseline captured before the work begins, with branded and non-branded reported separately. The complete method, free to use, is published in our measurement methodology, and the trackers that automate it are in our AI visibility tools comparison.
What Stopped Working, or Never Did
The playbooks still circulating recommend most of this.
- Keyword-stuffed pages built for engines rather than readers. The research found classic SEO manipulation largely ineffective inside generated answers.
- Buying placements. 0.3% of the citation supply, and shrinking as source-quality weighting improves.
- Seeded community mentions. Hunted by the platforms, deleted retroactively, and the citations die with the posts.
- Self-published rankings positioned as neutral. Retrieved today and working as an arbitrage, on the same enforcement path every earlier arbitrage took. They belong in a strategy only as a disclosed, honest comparison layer, never as the foundation.
The pattern across all four is the same: the engines are converging on sources that cannot be bought, because that is the only property that keeps their answers worth trusting. What changed and what did not is in our GEO versus SEO guide.
The Honest Timeline
Weeks, for extractable content winning uncontested long-tail questions. A quarter, for a first research-led campaign to produce its coverage: four to six weeks from kickoff to completed outreach, with placements landing during and shortly after that window.
Months, for corroboration to accumulate on contested commercial prompts, because visibility compounds across successive campaigns as each round of coverage extends the citation base engines retrieve from. No single campaign can guarantee being named, because naming is decided by synthesis across sources nobody controls. The honest unit of evaluation is the trend line against a documented baseline.
Anyone selling a faster path is selling one of the four things above, which makes the timeline the first question to put to any shortlist of AI SEO agencies.
FAQ
Can I get cited by ChatGPT without backlinks?
On uncontested long-tail questions, yes: extractable, well-sourced owned content can be retrieved and cited directly. On contested commercial questions, no: being named requires corroboration across independent sources, and earning presence in those sources is the same work that produces links and mentions.
Does ChatGPT cite differently from Perplexity and Gemini?
The retrieval blends differ, so the cited sets differ, and a brand's visibility varies across engines more than most teams expect. That variance is diagnostic: it tells you which engine's trusted sources you are missing from, which is why measurement runs per engine.
How do I know which sources decide the answers in my category?
Run the prompt panel and log every cited URL, then classify each source as earned, owned or rented. The resulting source map is the strategy document: it tells you where the next quarter's work goes. The full method is in our measurement methodology.
Is being cited by ChatGPT actually worth anything commercially?
Yes, and the value concentrates at the decision stage. Answer engines sit in the research phase of considered purchases, buyers check AI recommendations by clicking the cited sources, and the brands present in both the answer and its citations meet the buyer twice. Visibility here is a market-share contest scored in citations, which is the argument of our citation equity guide.
What is the single highest-leverage first step?
Capture the baseline. A call is a good place to start: a live review of how AI search and Google see your site today, and which competitors already appear in AI answers. Without a baseline, you can't prove what any later work changed.
References
- Ahrefs, https://ahrefs.com/blog/why-chatgpt-cites-pages/ (accessed 20 October 2026).
- Muck Rack, https://muckrack.com/blog/what-is-ai-reading-may-2026 (accessed 20 October 2026).
- Ahrefs, https://ahrefs.com/blog/ai-overview-brand-correlation/ (accessed 20 October 2026).
Earn the Citations. Track the Movement.
Find out what AI engines say about your brand, who they recommend instead, and what we'd change first.
Rather talk it through? Get in touch.